

How to Maintain AI Models without a Data Science Team
Most AI inspection tools were built assuming a data science team sits behind them. ReliVision was built assuming they don't — so the QA team owns the full maintenance loop, including validation and safe rollback.
- 4 steps
- Under 3 hours end to end
- No code
- Run by the QA team
The challenge
Why Model Maintenance Stalls
Four tasks owned by data science
In traditional AI workflows, model maintenance routes through a data science team. They own four recurring tasks:
- Monitor model performance
- Label and version datasets
- Retrain and validate models
- Deploy updated versions safely
But factories don't stay still
Each of these shifts can degrade a model overnight:
- A new supplier ships parts with a slightly different surface finish
- A defect type appears that wasn't in training data
- Throughput targets tighten the acceptable false-reject rate
When every update routes through a data science team, drift becomes downtime.
The shift
The Right Question
Most AI inspection tools were built assuming a data science team sits behind them. ReliVision was built assuming they don't.
The right question isn't “How do we replace data scientists?” It's:
How does the QA team own the full maintenance loop themselves — including validation and safe rollback?
The scenario in this guide
A customer inspecting router surfaces begins seeing a new scratch pattern the existing model was not trained to detect. Accuracy on that defect type drops, but the data science team is two weeks out. With ReliVision, the QA team opens the platform, adds examples of the new scratch pattern, fine-tunes the model and validates the updated inspection workflow — all in under three hours, end to end.
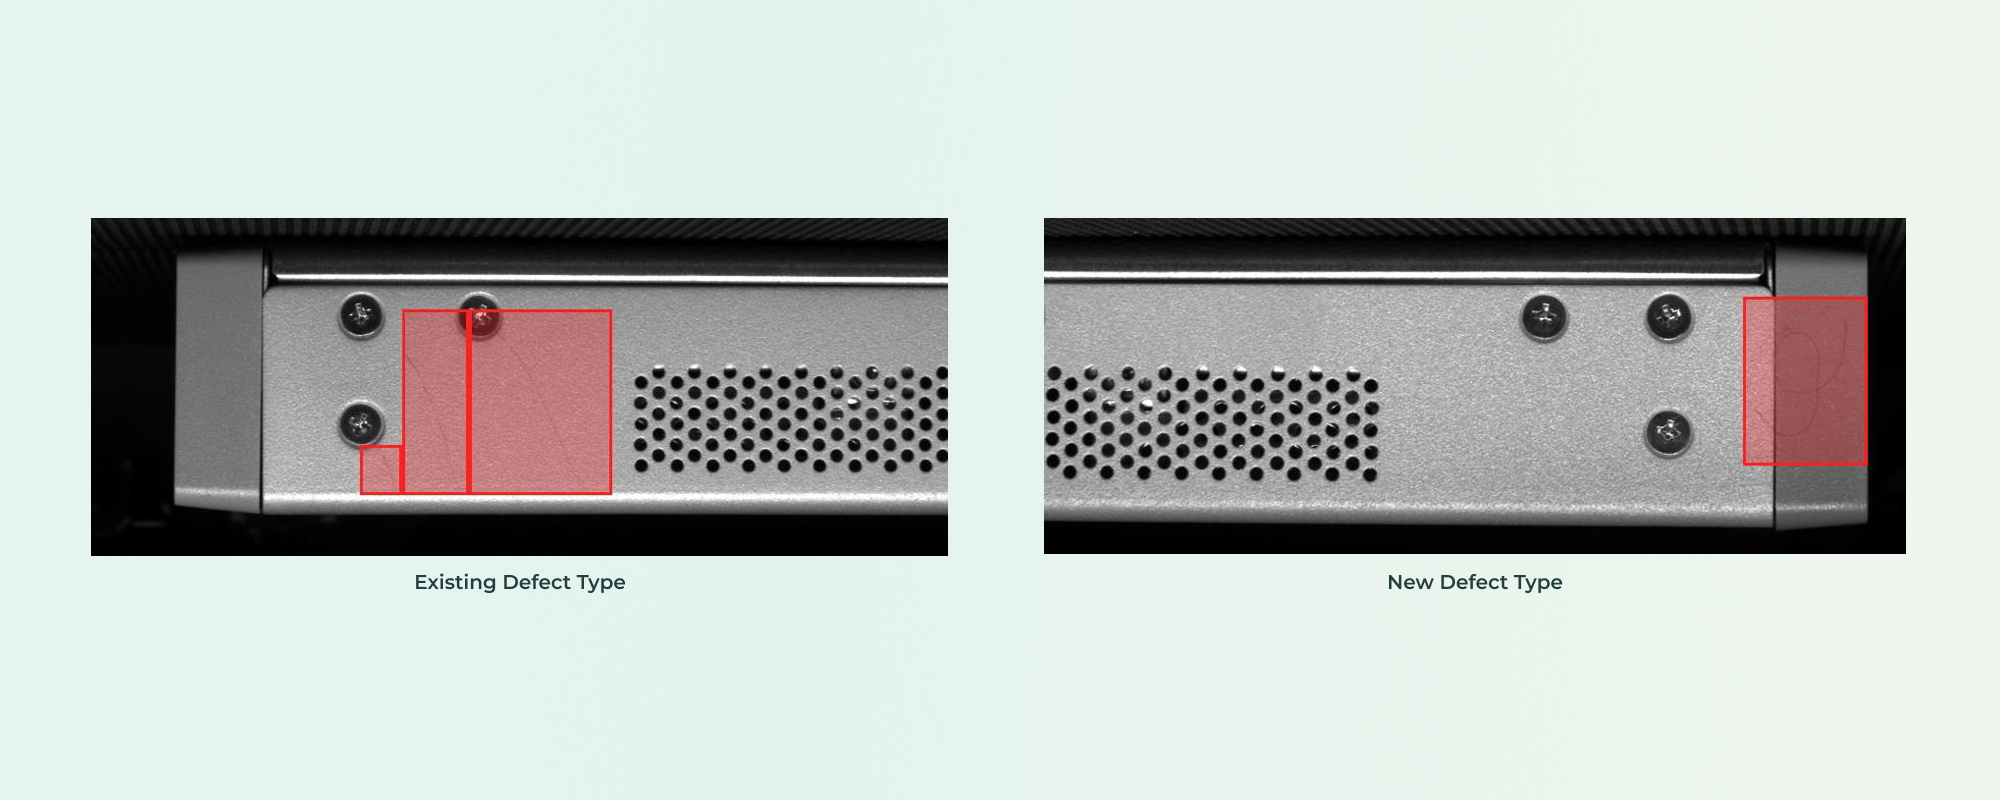
The loop
What Data Science Teams Do — and How QA Owns It in ReliVision
Monitor
ReliVision tracks prediction confidence, defect-class distribution and false-reject rate by station and shift.
Flag & Label
Operators flag misclassified images in the web HMI with one click. ReliUI versions the dataset automatically.
Fine-Tune
The operator launches ReliUI and runs a no-code fine-tune using the flagged dataset in under 30 minutes.
Deploy
Once the model is trained, the AI solution running on the shop floor is updated and pushed to ReliAudit with a single click.
Monitor
ReliVision tracks prediction confidence, defect-class distribution and false-reject rate by station and shift.
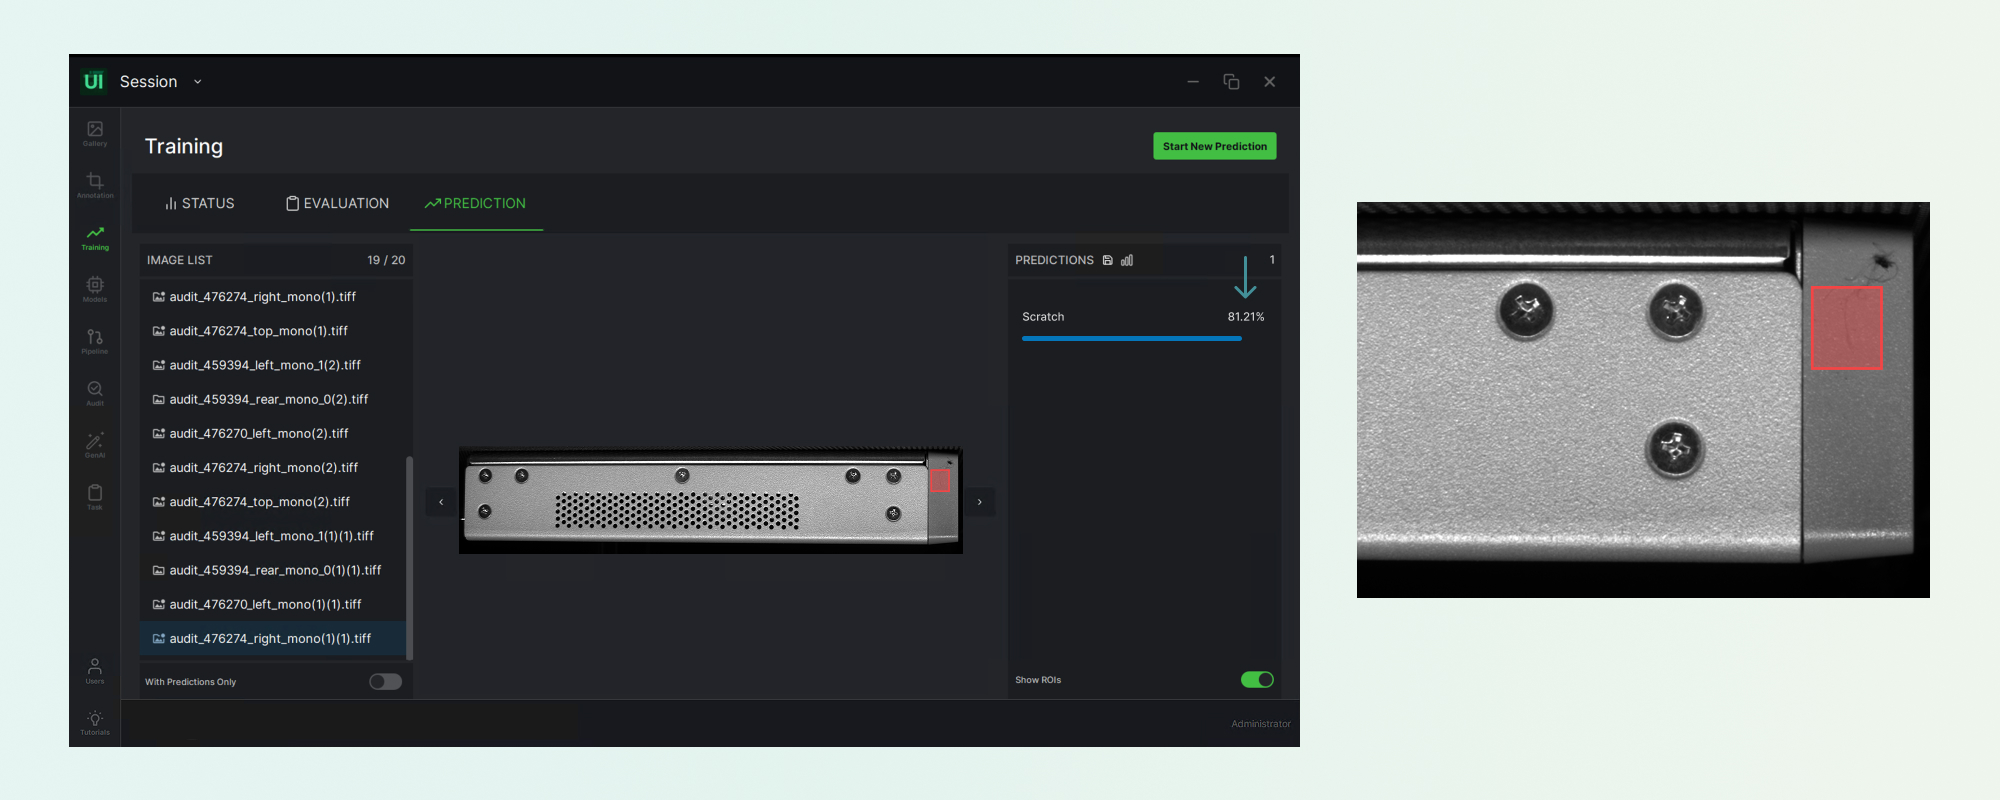
Flag & Label
Operators flag misclassified images in the web HMI with one click. ReliUI versions the dataset automatically.
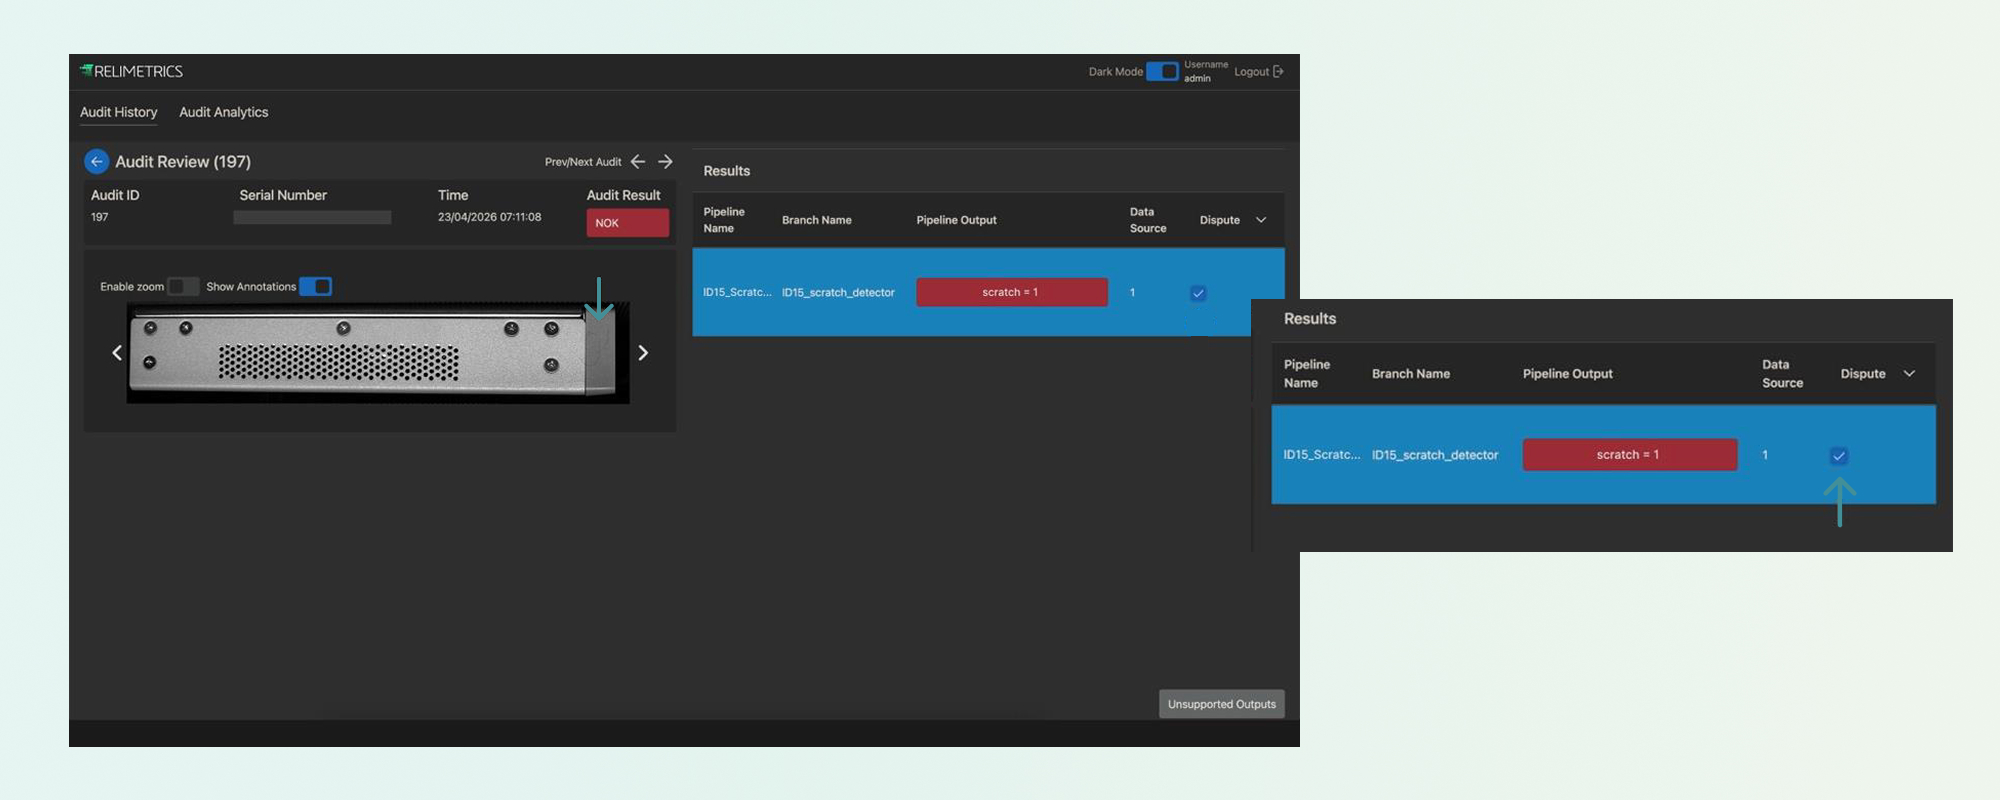
Outcome: router images showing the new scratch pattern are collected and labeled.
Fine-Tune
The QA team launches ReliUI and runs a no-code fine-tune using the flagged dataset in under 30 minutes.
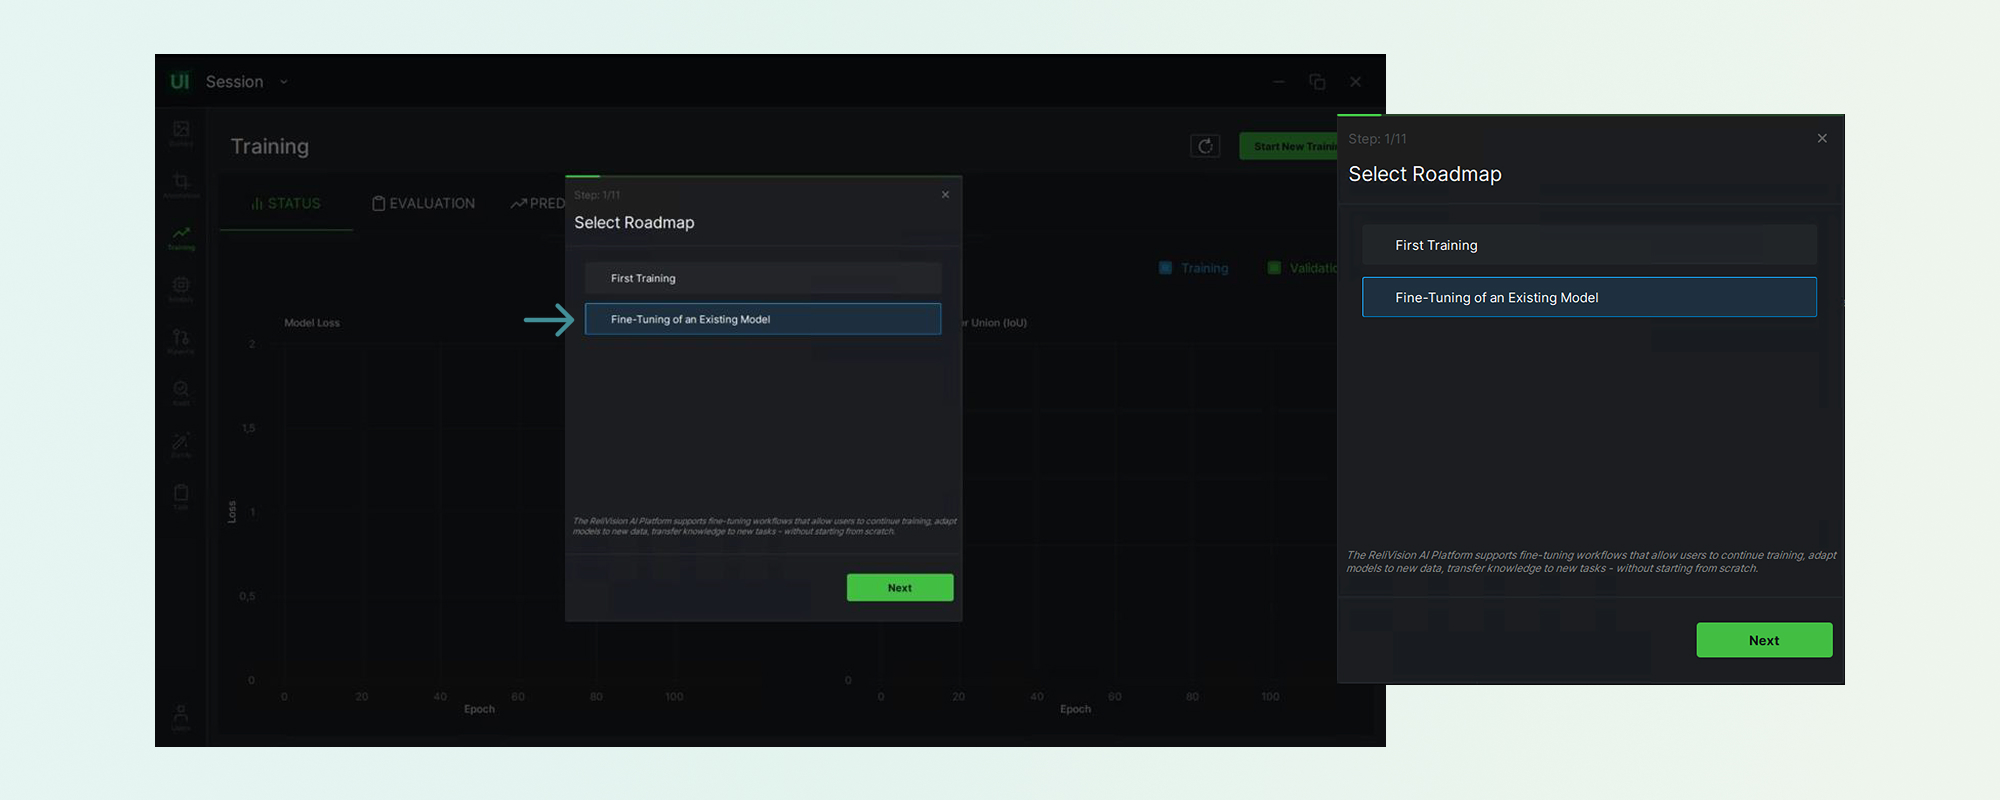
Outcome: a candidate model is ready in under 30 minutes. No Python. No code.
Deploy
Once the model is trained, the AI solution running on the shop floor is updated and pushed to ReliAudit with a single click.
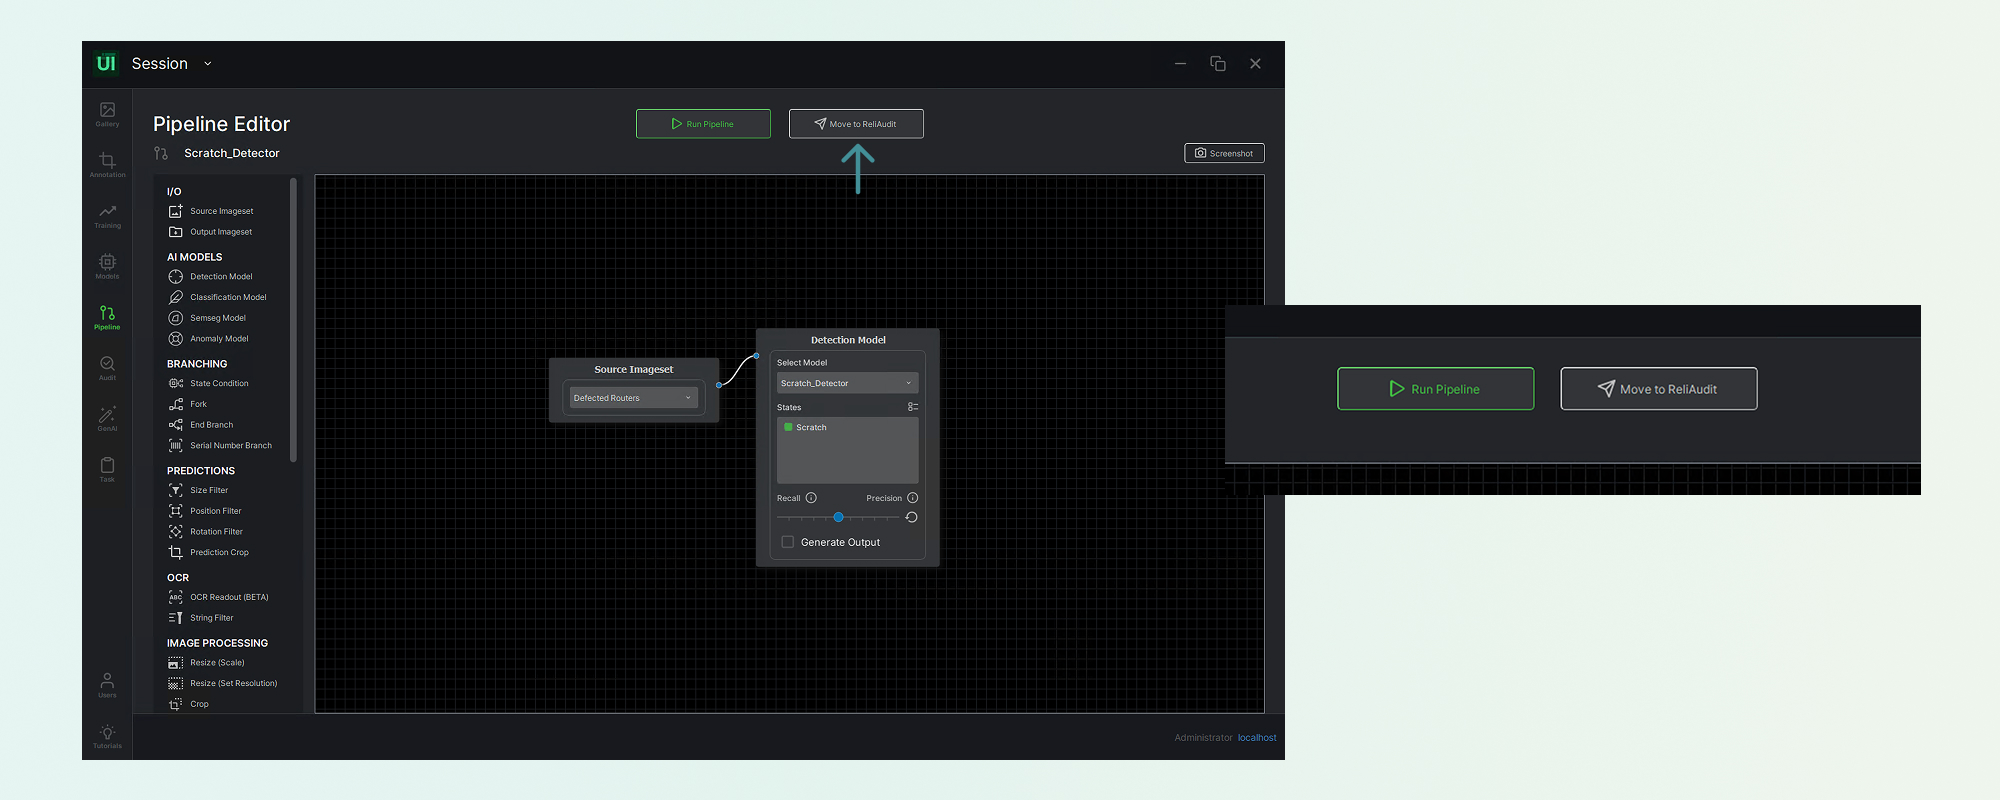
Outcome: the new model is deployed and detecting the new scratch pattern. The prior model is kept available for one-click rollback.
Impact metrics
What Changes in Practice
Model Update Turnaround
Days to weeks — waiting for data science team availability.
Under 3 hours — the QA team runs the full loop independently.
Team Dependency
Data science + DevOps — scripting, redeploying pipelines.
QA team only — no Python, no code.
Rollback Time
Hours to days — redeployment cycle, coordination required.
1 click — the prior model remains available for instant revert.
Why this is safe to run in-house
Three Guardrails Built Into the Loop
Side-by-side holdout evaluation
Every candidate model is evaluated against the live model. If precision drops on any class, promotion is blocked.
One-click rollback
The previous production model remains available. If the new model regresses on the line, revert in a single click.
Full audit trail
ReliAudit records dataset version, training run, evaluation report and approver for every promoted model.
Own your maintenance loop
Explore workflows, training, deployment and synthetic data best practices in the Knowledge Hub, or download ReliVision and run the loop on your own line.
Download ReliVision


